
The Growing Reality of Scaling Autonomous AI Agents
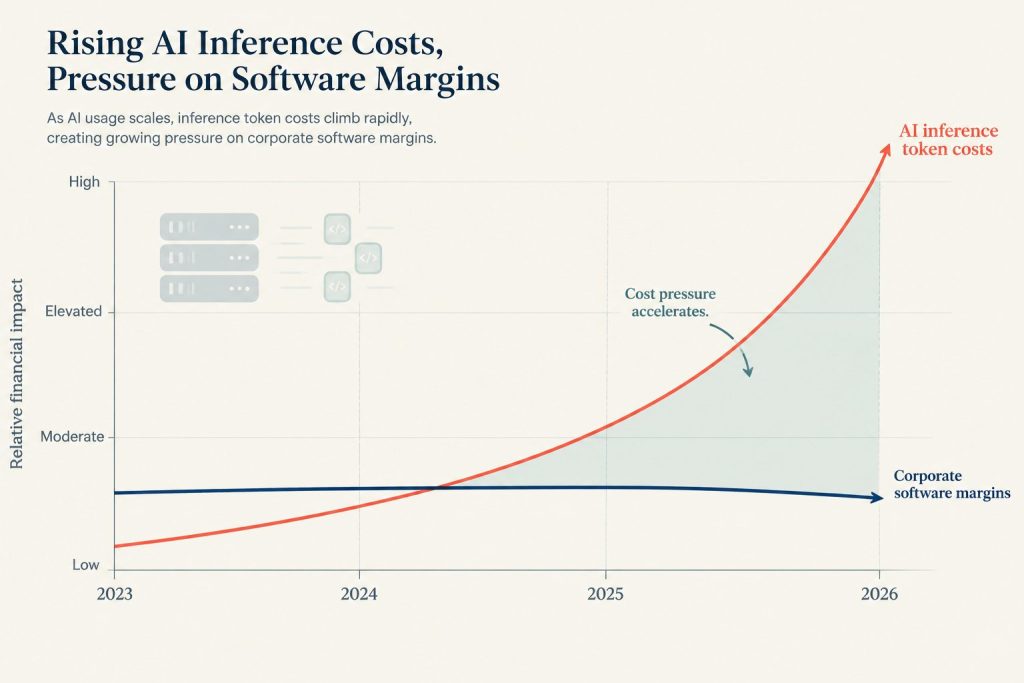
Uber’s reliance on automated decision-making and route optimization makes it an early case study for how agents can enhance efficiency while straining operational budgets. The billing structures provided by AI infrastructure vendors are often unclear. As companies scale they find that traditional cloud contracts do not map cleanly onto the fluctuating and often explosive nature of usage.
Enterprise Perspectives on Growing AI Expenses
Companies are looking for ways to manage these costs. They are exploring alternatives to raw token consumption. By optimizing engineering and utilizing caching mechanisms developers can reduce the number of tokens required for repetitive tasks. For example developers can implement a caching layer to prevent unnecessary repeat requests.
# Python-based logic for LLM request optimization
cache = {}

def get_optimized_response(query):
    # Check if a semantically similar query was already processed
    if query in cache:
        return cache[query]

    # Otherwise execute expensive API call
    response = call_ai_agent(query)
    cache[query] = response
    return response

# By implementing caching you avoid the
# redundant 24x token usage for standard tasks.
Mitigating the Financial Impact of High-Volume Tokenization
Many organizations are shifting toward “model distillation.” This means using less expensive models for specific tasks. This tiered approach allows companies to reserve the potent (and expensive) models for high-value reasoning while utilizing lightweight models for routine processing. See also: Dynamic LLM Routing: Cut AI Coding Costs & Latency.
The Road Ahead: Balancing Innovation and Profitability
The warning issued by financial experts regarding a 24-fold increase in token demand is a necessary reality check. The next phase of the AI revolution will be defined by cost-efficiency than sheer capability. Companies must adapt to this fiscal reality to ensure long-term viability in an increasingly agent-driven future.
Ultimately the challenge of tokenized billing is a reminder that computing power is not a limitless utility. Autonomous agents hold the promise of transforming productivity across every sector.. The transition requires a more nuanced approach, to resource management. See also: De-Googling Android: The Harsh Reality of App Dependencies.
The obvious countermeasure is routing: our dynamic LLM routing guide shows how to cut inference spend, while CursorBench 3.1 measures the AI editors competing for that budget.
The obvious countermeasure is routing: our dynamic LLM routing guide shows how to cut inference spend, while CursorBench 3.1 measures the AI editors competing for that budget.
Related Stories
De-Googling Android: The Harsh Reality of App Dependencies
Why is de-Googling modern smartphones so difficult? We document push notification failures, banking security blocks, and the 2…

Gotham Sequel Villain Explores Real-World AI & Cyber Threat
The upcoming Batman Gotham sequel introduces a tech-obsessed antagonist reflecting contemporary fears of algorithmic surveillance and cyber warfare.
Global Police Dismantle AudiA6 Ransomware Crypto Launderer
International law enforcement agencies seize servers and millions in crypto belonging to AudiA6, a premier laundering syndicate for…